Technology
Why Non-Emergency Medical Transportation is Critical in Healthcare

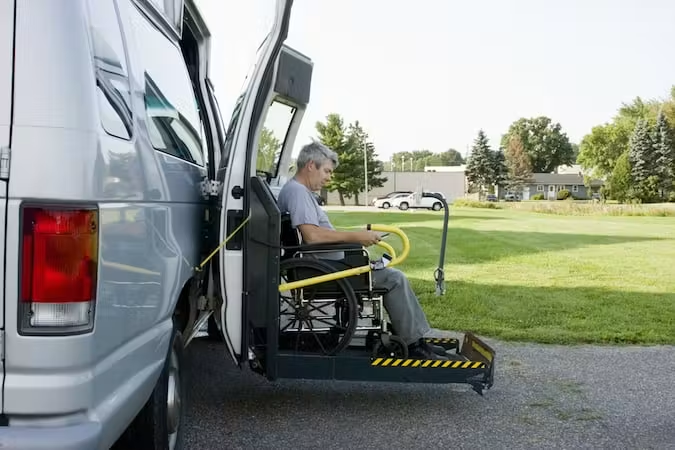
A healthcare network can employ world-class clinicians and deploy state-of-the-art diagnostic imaging suites, but those assets remain entirely useless if a patient cannot physically reach the point of care. While emergency services handle high-acuity trauma transit, a much larger, quieter logistical gap exists for chronic, elderly, and mobility-impaired populations.
Non-Emergency Medical Transportation (NEMT) has transitioned from a minor administrative convenience into a mission-critical component of modern healthcare delivery. As health systems shift toward value-based care models, optimizing the patient transit layer is no longer optional; it is a financial and operational imperative.
Missed Appointments and Revenue Leaks
For specialized clinical environments and outpatient facilities, patient no-shows are a persistent drain on operational revenue. A single missed appointment leaves expensive equipment idle, disrupts physician scheduling patterns, and artificially inflates patient waitlists.
Statistics indicate that transportation barriers prevent millions of individuals from accessing necessary medical care annually. When chronic patients (requiring routine dialysis, oncological radiation, or post-surgical wound care) miss appointments due to a lack of reliable transit, their underlying conditions inevitably destabilize.
This creates a highly predictable, high-cost cycle: preventable medical non-compliance leads directly to an emergency department admission. By establishing structured, reliable NEMT corridors, healthcare organizations replace these costly acute-care surges with predictable, managed outpatient visits. This stabilizes internal workflows and protects consistent revenue streams across multi-site health systems.
Driving Down Hospital Readmission Rates
Under the Hospital Readmissions Reduction Program (HRRP), hospitals face financial penalties if specific patient populations are readmitted within a 30-day window following discharge. A primary catalyst behind these avoidable readmissions is the total breakdown of post-discharge care plans. They are frequently caused by a lack of transit options to pick up prescriptions or attend follow-up clinical audits.
Integrating a dedicated NEMT logistics framework directly into the inpatient discharge workflow ensures a seamless handoff from the bedside to the home environment. When a patient leaves the facility with their immediate post-acute transit pre-arranged, compliance rates climb sharply. Ensuring that a vulnerable patient actually arrives at their 48-hour follow-up appointment is the single most effective factor. A case management team can use it to clear bed capacity and safeguard hospital resource margins.
The Complexities of Modern NEMT Dispatching
On paper, arranging a non-emergency ride sounds like a basic taxi dispatch task. In practice, medical transportation logistics involve an intricate, high-stakes matrix of clinical compliance, passenger constraints, and varying fleet capabilities.
- Divergent Vehicle Acuity Requirements: A single shift may require a mix of standard ambulatory sedans, wheelchair-accessible vehicles (WAVs) with specialized hydraulic lifts, and non-emergency gurney vans equipped with specialized monitoring tools.
- Complex Multi-Payer Authorization Environments: Managing rides funded via state Medicaid programs, private managed care organizations (MCOs), or billing codes, and strict verification windows.
- Dynamic Patient Scheduling Realities: Unlike standard delivery logistics, medical transits are highly volatile. A clinical procedure that runs thirty minutes long or a delayed physician sign-off instantly de-synchronizes a driver’s subsequent pickup schedule.
To resolve these daily operational friction points, healthcare networks are moving away from legacy manual booking methods and fragmented spreadsheet trackers. Institutes are actively investing in custom healthcare software development to build specialized NEMT dispatch platforms. Such platforms automate vehicle assignment, optimize routing based on live traffic, and integrate directly with electronic health records (EHR).
Smart Software Integration Changes Patient Logistics
Resolving systemic transportation bottlenecks requires more than just adding more vehicles to a fleet or hiring more drivers. True efficiency stems from intelligent coordination and data visibility. Modern Non-Emergency Medical Transportation depends entirely on custom software solutions that bridge the information gap between clinics, drivers, and patients.
- Dynamic Geolocation and Auto-Routing: Specialized software engines analyze real-time vehicle locations and historical traffic patterns to assign incoming ride requests instantly, removing manual guesswork from dispatch desks.
- End-to-End Fleet Visibility: Real-time tracking modules give floor nurses and case managers precise arrival updates, completely eliminating the need for continuous follow-up phone calls to check a vehicle’s status.
- Automated EHR Trigger Arrays: Modern software integration allows a trip request to be automatically generated. The moment a doctor inputs a discharge order or schedules a recurring outpatient therapy inside the patient’s record, the workflows initiate.
- Consolidated Multi-Vendor Orchestration: Instead of relying on a single transport source, integrated networks connect internal fleets and third-party NEMT vendors. It transforms into a single operational interface, scaling capacity dynamically based on daily demand surges.
Conclusion
Patient transportation is no longer a peripheral logistical task to be outsourced and ignored. It is an active operational vector that dictates a health system’s bed turnover efficiency, readmission vulnerability, and overall clinical experience.
Hospitals that continue to manage their patient care tracks through unoptimized, manual legacy processes will continue to see their operational margins eroded. By employing data-driven Non-Emergency Medical Transportation platforms, healthcare providers resolve the challenges and escalate essential medical care.
Building these high-performance networks requires an engineering partner capable of designing secure, compliant software environments tailored to complex workflows. At Unique Software Development, we engineer custom enterprise applications built to meet the rigorous scale, security, and integration demands of modern healthcare infrastructure.

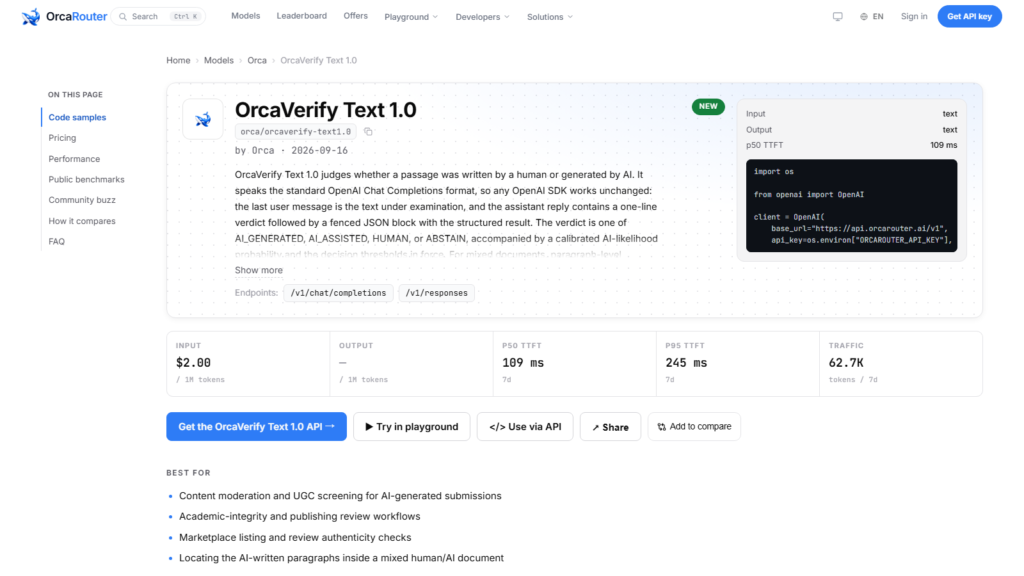
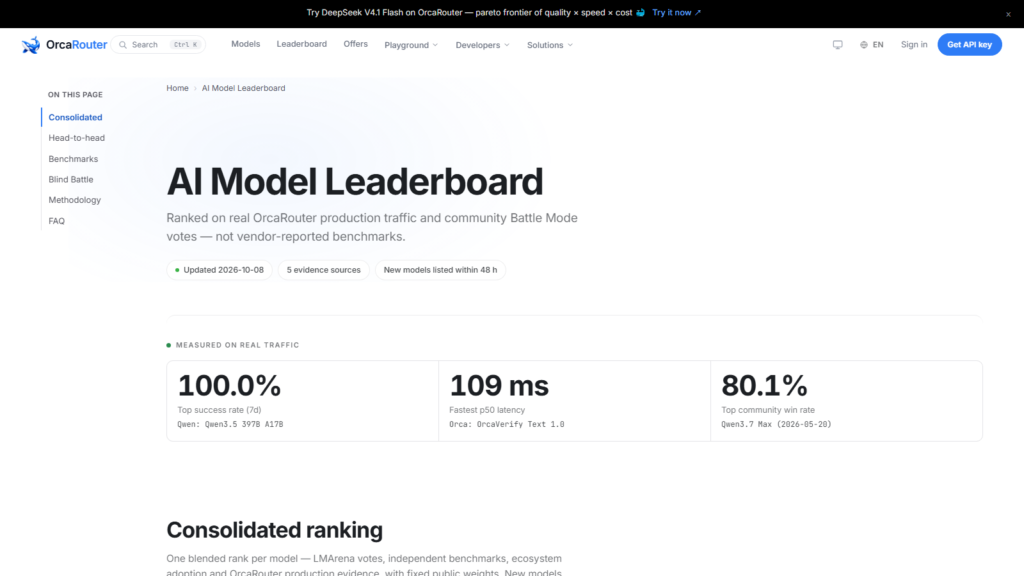
On OrcaRouter we host the OrcaVerify Text 1.0 model — our verification-specialized model, shipped on September 16, 2026, priced at $2 per million input tokens with its directory entry listing no output price and no context window. In production its p50 time-to-first-token is 115 milliseconds — the fastest first response in this whole cluster of 32 cards — and its seven-day token volume is 82.5 thousand. It is our own product, so no independent third-party score exists to cite; the production record above is the evidence, with the live telemetry on the linked page.
A model whose whole case is a 115-millisecond first token is a model with one number to defend — and this article is about why that one number is enough for the job it names.
The fastest first token on the board
The number is 115 milliseconds, and it is not close: across the 32 cards in this cluster — text flagships, code specialists, audio and video models — no other card’s p50 first token comes within an order of magnitude of it. The fleet’s next-fastest cards sit in the 1.27-second range, and the slowest card waits ten seconds before its first token. That is the gap this article is built on: a first response in 115 milliseconds is not a faster version of the fleet’s answers, it is a different class of answer, and it is the fastest first token in this cluster.
The honest framing is that this is our own telemetry, and the article says so plainly. Because OrcaVerify Text 1.0 is our product, there is no independent third-party benchmark to cite, and the 115-millisecond figure is measured on our own endpoint. What the record does prove, without any external confirmation, is that a verification call can round-trip its first token at the speed a human perceives as instantaneous — and that is the entire job of this card.
The verification card, measured
| card | kind | pricing | context | p50 TTFT | 7-day tokens |
| OrcaVerify Text 1.0 | verification | $2 per 1M in | not listed | 115 ms | 82.5K |
| OrcaCyber Zero 1.0 | security | $3 / $7.50 | 1M | 2.93 s | 7676.6M |
| MiniMax-H3 | audio | $0.08 / second | not applicable | 406 ms | 100.6K |
Pricing, context entries and the p50 and token figures are from the linked pages on the platform; all three cards include our own products, and the rows are listed to show the shape of the first-token spectrum rather than to compare like for like. The table places the 115-millisecond reading against the fleet’s other fast cards: the audio card at 406 ms, the security card at 2.93 seconds — a span from an instant to three seconds across the same platform. The verification card sits at the instant end, and its 82.5K weekly tokens say its job is not volume; it is speed, used where a check must not slow a pipeline down.
What a 115-millisecond check buys
A verification call is a gate, and a gate has a budget. In a pipeline that submits a verification on every record — every transaction, every claim, every entry — the check’s latency multiplies across the whole run, and a 115-millisecond first token keeps the gate from becoming the pipeline. The card is priced accordingly: $2 per million input tokens with an input-only rate card, which says the verification pass is meant to be cheap and frequent, not heavy and rare. Its directory entry lists no output price and no context window, and this article reports that plain fact: it is a check, not a generator.
The design intent is legible in the pairing. A first token at 115 milliseconds for a gate that most of the time answers with a verdict, priced per input token, is the shape of a model made to sit inside a loop and be called a million times. The 82.5K weekly tokens on the linked page are the honest counterweight — the card is new and its workload is a specialist’s — but the speed is the point, and the speed is what the production record proves.
The workloads that call it a million times
The profile that fits OrcaVerify Text 1.0 is the profile that cannot afford to wait: verification gates inside larger pipelines, real-time checks in request flows, classification and vetting of short inputs where a slower model would throttle the whole system. For each, the 115-millisecond first token is not a feature, it is the requirement — the gate exists to be cheap and instant, and any model that adds a second of latency changes the arithmetic of the loop. The $2-per-million input rate keeps that gate affordable at volume.
The honest boundary mirrors the card’s own record. It is not built for generation, and its 82.5K weekly tokens show a specialist’s scale rather than the fleet’s volume. It is our own product, so its evidence is our own production record — the fastest first token in this cluster of 32, measured on our own endpoint. For a pipeline that needs its gate instant and cheap, that record is the whole case, and the linked page is where a buyer reads it.
One arithmetic worth doing before the verdict is what 115 milliseconds does to a loop’s budget. A gate called a hundred thousand times a day spends about three hours of cumulative first-token latency at 115 ms; the same gate at the fleet’s 1.27-second pace would spend more than a day and a half — and at the ten-second card’s pace, nearly twelve days. For a pipeline that runs checks on every record, the difference is not whether the gate feels fast, it is whether the gate stays invisible to the run. The 115-millisecond figure earns its headline the same way a cheap gate earns its keep: by being the part of the pipeline nobody has to think about. The 82.5K weekly tokens say the market is just beginning to put that load on it.
The takeaway
OrcaVerify Text 1.0 is our verification-specialized model: $2 per million input tokens, an input-only rate card, no listed context window, a p50 first token of 115 milliseconds — the fastest in this cluster of 32 cards — and an 82.5K seven-day token volume. It is our own product, so no independent score exists to cite, and the production record is the evidence. That record says a verification gate can answer in well under a quarter of a second, priced per input token for volume. If your pipeline needs a check that does not make it wait, this is the card — live, with the telemetry on the linked page.
Sourcing note: OrcaVerify Text 1.0 is our own product, hosted on our own platform, so all figures — the $2 per million input price, the input-only rate card, the p50 time-to-first-token and the seven-day token volume — are OrcaRouter production data from the linked model page as of 2026-10-08. The claim that 115 ms is the fastest first response in this cluster of 32 cards is based on the p50 readings recorded across the linked model pages on the same platform as of the same date. No independent third-party benchmark exists for this card, and none is implied. All checked 2026-10-08.
Technology
An In-Depth Comparison of Bluetooth and LoRa Communication: Selection Guide for IoT Engineering

I. What are BLE, LoRa Private Protocols, and the LoRaWAN Standard Protocol?
Bluetooth Low Energy (BLE)
Bluetooth Low Energy (BLE) is a mainstream short-range communication solution in the consumer electronics and smart hardware sectors, ideal for indoor, short-range human-machine interaction. Since smartphones come with native Bluetooth support, devices can connect directly to mobile apps without the need for intermediate equipment like gateways or servers. The physical layer supports a maximum transmission rate of 2 Mbps, OTA firmware upgrades, and high-frequency waveform acquisition; customizable connection intervals allow for millisecond-level real-time response.
Bluetooth operates in the 2.4 GHz frequency band; signals suffer significant attenuation when passing through walls or the human body, limiting reliable communication range to just 10–30 meters (or a maximum of 100 meters in open environments). Bluetooth Mesh networking has limitations: as the number of nodes increases, channel congestion and latency rise, making it unsuitable for high-density, large-scale sensor networks. Ebyte’s E104 series Bluetooth modules are optimized for low power consumption, achieving microampere-level standby current, making them ideal for small, battery-powered smart terminals.
LoRa Private Protocols
LoRa private protocols are custom transparent transmission solutions based on the LoRa physical layer. Unconstrained by standardized protocol stacks, they offer flexible deployment and simple development. They are frequently used in lightweight IoT scenarios such as industrial monitoring, enclosed factory sites, and long-range data transmission in the field.
Leveraging LoRa spread-spectrum technology, these protocols achieve receiver sensitivity of up to -148 dBm. Combined with Sub-GHz low-frequency bands, they offer strong obstacle penetration and diffraction capabilities, mitigating signal issues caused by architectural obstructions or “dead zones” in factory areas. They utilize serial transparent transmission, eliminating the need to port complex protocol stacks; simple configuration enables wireless transparent transmission over several kilometers, thereby shortening project development cycles.
This solution cannot communicate directly with mobile devices like smartphones and requires a gateway for protocol conversion. Lacking a standardized MAC layer scheduling mechanism, simultaneous communication by a large number of nodes can easily lead to channel conflicts; developers must design their own anti-collision mechanisms, making this approach unsuitable for ultra-large-scale scenarios involving simultaneous multi-node communication. Ebyte’s E22 series represents the corresponding hardware products. LoRaWAN Standard Protocol
LoRaWAN is a standardized MAC-layer networking architecture built upon the LoRa physical layer. It features unified communication rules, encryption mechanisms, and device management logic, making it suitable for large-scale, wide-coverage, and standardized IoT networking scenarios.
The protocol supports ADR (Adaptive Data Rate) and multi-channel parallel transmission, allowing a single gateway to support thousands of simultaneously connected end-devices. It mandates AES-128 encryption, complies with international standards, and integrates with various third-party IoT cloud platforms. Ebyte’s E77 series features a built-in, full protocol stack; when paired with E8xx series gateways, it enables the rapid deployment of large-scale monitoring networks for campuses or cities.
Its drawbacks include a high development barrier, strict requirements for protocol stack logic and timing, and lengthy deployment and debugging cycles. In the mainstream Class-A mode, gateways cannot actively issue commands; instead, they rely on the end-device’s uplink window to complete downlink communication, resulting in latency on the order of seconds—making it unsuitable for real-time device control.
II. Core Characteristics of the Three Communication Solutions
1. Communication Range: BLE effective range is within 100 meters; LoRa private transparent transmission can reach 3–10 km; LoRaWAN standard protocol can reach 3–5 km.
2. Operating Frequency Band: BLE uses 2.4 GHz; both LoRa private transparent transmission and LoRaWAN use Sub-GHz bands.
3. Real-time Performance: BLE operates at the millisecond level with excellent real-time performance; LoRa private transparent transmission operates at the second level with good real-time performance; LoRaWAN has average real-time performance, as it is influenced by heartbeat cycles.
4. Connectivity: BLE supports direct connection to smartphones without a gateway; neither LoRa private protocols nor LoRaWAN support direct smartphone connections, requiring a gateway for relay.
5. Network Scale: BLE has limited networking capacity, and Mesh networks are prone to congestion with many nodes; LoRa private protocols lack MAC scheduling, making them prone to collisions when many nodes transmit concurrently; LoRaWAN supports thousands of end-devices per gateway, making it suitable for massive device connectivity.
6. Development Difficulty: BLE is easy to deploy; LoRa private protocols offer simple and flexible development; LoRaWAN protocols are complex, presenting a high barrier to entry for development and debugging. 7. Security Capabilities: The LoRaWAN protocol mandates AES-128 encryption; in contrast, BLE and proprietary LoRa protocols do not define a unified, mandatory encryption standard.
III. Application Scenarios for the Three Communication Solutions
Bluetooth Low Energy (BLE) Application Scenarios
Suitable for projects requiring short-range human-machine interaction, direct smartphone control, low latency, and medium-to-high speed data transmission.
Typical applications: Smart locks, portable testing instruments, indoor lighting control, and other short-range devices.
Proprietary LoRa Protocol Application Scenarios
Suitable for projects involving a limited number of nodes that prioritize long-range transmission and rapid development/deployment, such as data transparent transmission within enclosed industrial sites or in the field.
Typical applications: Field monitoring and remote sensor data backhaul from industrial sites.
LoRaWAN Standard Protocol Application Scenarios
Suitable for large-scale IoT projects requiring massive concurrent device access, wide-area coverage, unified cloud-based management, and standardized communication security.
Typical applications: Smart city monitoring, comprehensive smart meter reading, and asset tracking.
Note: Selecting a wireless IoT solution essentially involves balancing transmission bandwidth, device power consumption, and communication range; the choice must account for both physical performance limits and architectural constraints.
IV. Ebyte Product Recommendations
Based on the technical characteristics of BLE, proprietary LoRa transparent transmission, and LoRaWAN standard protocols, as well as specific application requirements and Ebyte product compatibility, we offer modules tailored for short-range interaction, long-range transparent transmission, and large-scale wide-area networking. Specific product recommendations are as follows:
E104 Series: Features a high-performance BLE chip operating in the 2.4GHz band with an effective communication range of 10–30 meters. It supports 2Mbps high-speed transmission, millisecond-level low latency, firmware OTA upgrades, and ultra-low power consumption (microampere level), enabling direct smartphone connectivity without a gateway. Suitable for short-range human-machine interaction scenarios such as smart locks, portable testing instruments, and indoor lighting control. E22‑170M22S: Utilizes mature LoRa spread-spectrum technology and operates in the Sub‑GHz band. It offers a transmit power of 22–30 dBm and a maximum communication range of 3–10 km. Featuring transparent serial data transmission, it eliminates the need for complex protocol stacks, ensuring simple development and flexible deployment. It supports point-to-point and point-to-multipoint long-range transparent transmission without requiring a gateway, making it ideal for low-cost, long-range applications with limited nodes, such as field monitoring and remote sensor data backhaul in industrial facilities.
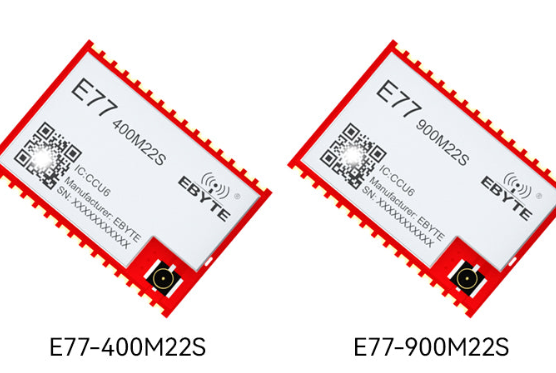
E77 Series: Powered by the STM32WLE5 RF SoC, this series natively supports the LoRaWAN standard protocol and covers mainstream IoT frequency bands (400 MHz/433 MHz/915 MHz) with a communication range of 3–6.5 km. It supports ADR (Adaptive Data Rate) and AES‑128 encryption, allows for massive concurrent terminal access via a single gateway, and integrates seamlessly with cloud-based management and data analytics. It is the preferred choice for large-scale wide-area networking projects, such as smart city monitoring, comprehensive smart metering, and equipment/asset tracking.

Nine o’clock on a Monday in the back office of an independent shop, and three windows are open on the laptop. One is the till system’s weekly sales export. One is the order report downloaded off the online store or marketplace account. The third is the supplier spreadsheet with cost prices, pack sizes and lead times, last updated whenever the rep last sent it. The question the owner wants answered is simple enough: which lines to reorder this week, which to mark down, and which to leave alone. Getting that answer out of the three windows is where the morning goes.
Each system was bought for a specific job and does it well. None was designed to agree with the others.
Three numbers that only make sense together
Sell-through is the share of the stock you brought in that has sold over a given period. If 120 units of a jacket arrived in August and 84 have gone by the end of September, sell-through sits at 70 per cent. On its own that looks healthy. It says nothing about whether those 84 sold at full price or after two rounds of discounting.
Margin after returns and discounts fills that in. Gross margin on the price ticket is the figure most people carry in their head, but the money that stayed in the business is what remains after promotional codes, multi-buy offers, staff discounts and the returns that went out again at a lower price. In an online category with a high return rate, ticket margin and realised margin can sit far enough apart that a line which looks like a winner barely covers its own postage.
Weeks of cover is the third. Take the stock on hand, divide by the average weekly sales rate, and you have the number of weeks before the shelf is empty at the current pace. Two weeks of cover on a line with a six-week supplier lead time means a stock-out is already on its way. Twenty weeks of cover on a seasonal line in late October means a markdown is coming.
Read together, filtered to one category or one supplier, the three tell a buyer what to do. Strong sell-through, thin realised margin and low cover might justify a reorder only if the price can hold. Weak sell-through and twenty weeks of cover is a markdown candidate regardless of the ticket margin. Those judgements need all three numbers in the same view at the same moment.
Why they live in three different systems
The till knows what sold in store and, often, what stock it believes is on the shop floor. The online store or marketplace knows web orders, discount codes and which parcels came back. The supplier sheet knows cost prices and lead times. Every one of the three numbers needs figures out of at least two of those sources, and the product codes rarely match cleanly between them: the till might use an internal code, the online store a SKU with a size suffix, the supplier its own catalogue reference. Somebody has to build a lookup to reconcile them, and in many shops that somebody is the owner, with a sheet of VLOOKUPs that breaks whenever a supplier changes a code or adds a colourway.
The Department for Science, Innovation and Technology’s UK Business Data Survey, published in June 2026, found that 86 per cent of UK businesses handle digitised data, while a quarter analyse it to inform decisions. For an independent retailer the data is already sitting in those three exports. The work is in joining it.
Spreadsheets handle the first version of this well. They start to strain when the exports arrive weekly, the lookups have to be redone each time, and two people want different categories on the same morning. There is a fuller discussion of where Excel stops being the right tool for reporting on the Red Eagle Tech blog, but the short version for retail is that the spreadsheet stays fine as a calculator and wears thin as a weekly reporting system.
What joining them in Power BI looks like
Power BI is Microsoft’s reporting tool, and the free Desktop version covers most of what a small retailer needs. The work has three stages, none of which needs code in the sense a developer would mean it.
The first stage is bringing the files in. Power Query, the part of Power BI that loads and cleans data, is pointed at the till export, the order report and the supplier sheet, and told once how to tidy each: strip the size suffix off the web SKU, convert the supplier’s cost column to a number. Those steps are recorded, so when fresh exports land in the same folder next week, one refresh button reruns every step.
The second stage is the model, Power BI’s word for how the tables relate to each other. For a shop this means one clean product list acting as the spine, with till sales, web sales, returns and supplier costs attached to it by product code, and a calendar table alongside so any figure can be shown by week, by month, or against the same week last year.
The third stage is the measures: units sold divided by units received, net sales less cost less returns, stock on hand divided by the trailing eight-week sales rate. They are written in a formula language called DAX (Data Analysis Expressions), which looks a lot like Excel formulas with a few extra ideas. Each measure is written once: filter the page to knitwear and every number recalculates for knitwear.
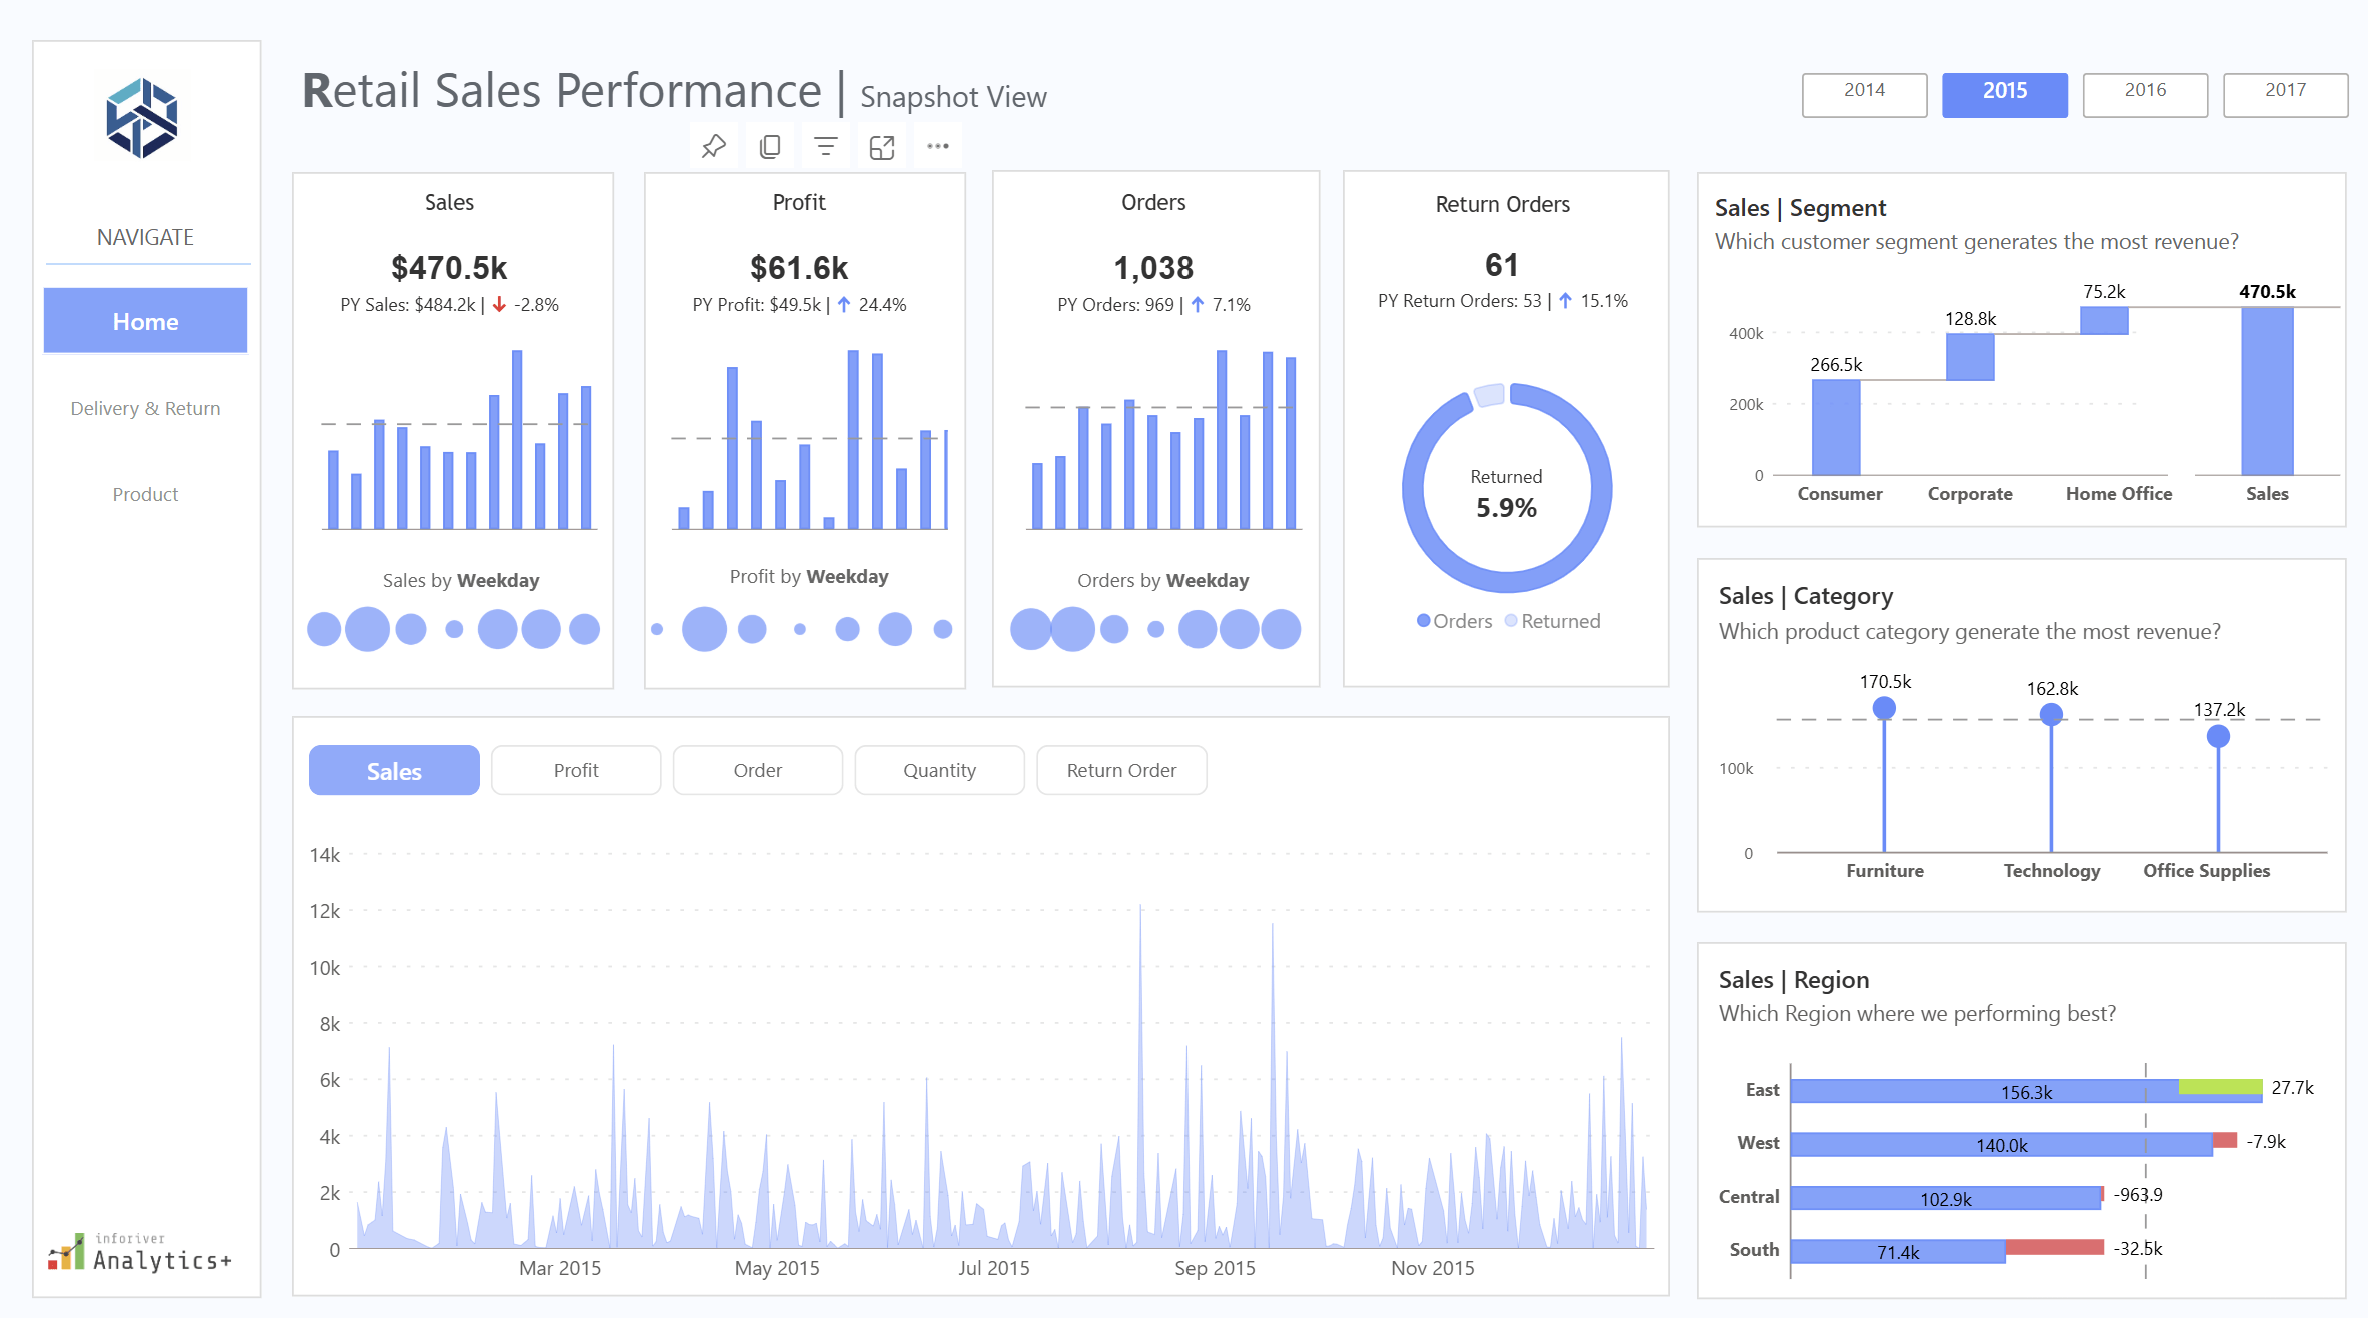
The result is a single page: a table of product lines with sell-through, realised margin and weeks of cover beside each other, and a slicer at the top for category, supplier and channel. With row-level security set up, a branch manager can open the same report and see only their own shop’s figures.
Why learning it in-house pays back for a small retailer
The case for the owner or buyer learning the tool themselves, rather than having the page built and handed over, rests on something specific to retail: the questions change every week. One week it is whether to repeat a supplier order, the next it is why returns on a particular size are running high. Someone who built the model can add it in an afternoon. Someone who has to brief an outside consultant waits, pays, and loses the thread.
There is also the matter of knowing the data. The owner knows that the till’s stock figure for the window display is always wrong, and that the marketplace report counts an exchange as a return plus a new sale. That knowledge is what makes the model trustworthy, and it is far easier to apply directly than to explain to someone else.
Training is the piece that makes this possible. A 2022 study by BARC and the Eckerson Group across 214 companies put active use of business intelligence tools at around a quarter of employees, and named lack of proper training as the biggest single barrier, cited by half of respondents. The tool sits on the laptop; the skill to use it is what has to be acquired.
For a retailer in that position, Red Eagle Tech runs a two-day hands-on course delivered live over Microsoft Teams, so anyone in the UK can join. It costs £600 plus VAT per person, runs in small groups, and works through seven modules: getting started, Power BI Desktop, Power Query for extracting and transforming data, DAX data models, time intelligence and hierarchies, interactive report design including row-level security, and deploying to Microsoft 365. The trainer has led Power BI training across a FTSE 100 company. Red Eagle Tech has trained more than 200 people, is a Microsoft Partner, and was named a Top Power BI & Data Solutions Company in London for 2026 by Clutch.
Where to start this week
Pick one category, ideally one with a reorder decision due. Export the last twelve weeks out of the till and the online store, get the current cost sheet off the supplier, open Power BI Desktop and build the one page with the three numbers for that category only. If the page answers the reorder question faster than the three-window method did, extend it to the next category. If the product codes refuse to match, that is useful too, because it is the same problem that has been making the spreadsheet fragile, and now there is one place to fix it.

The Conflicts Nobody Thinks To Declare

How to Source European Bricks for UK Building Projects

How Automation is Reshaping the Global Food & Beverage Packaging Industry in 2026
Who Is Shameera? All You Need To Know About Charli XCX’s Mother
Who Is Gulliver Flynn Oldman? The Untold Story of Sir Gary Oldman’s Son
Meet Rosemary Turner: The Mother of Actor Callum Turner
-
Biographies8 months ago
Who Is Shameera? All You Need To Know About Charli XCX’s Mother
-
Biographies8 months ago
Who Is Gulliver Flynn Oldman? The Untold Story of Sir Gary Oldman’s Son
-
Biographies8 months ago
Meet Rosemary Turner: The Mother of Actor Callum Turner
-
 Biographies6 months ago
Who is Alexandra James? Inside The Life of Jeremy Clarkson’s Former Partner
-
 Biographies8 months ago
Who is Todd McRae? Meet Tate McRae’s Father
-
 Biographies7 months ago
Who Is Daniel Mara? The Untold Story of Kate Mara’s Private Sibling
-
 Celebrity8 months ago
Who Is Peter Hernandez? The Real Story of Bruno Mars’ Father
-
 Biographies8 months ago
Who Was Adrian Mayers? The Untold Life of A$AP Rocky’s Late Father